You asked AI to help organise Monday’s meeting. It wrote a lovely invitation. You still had to find a time, check everyone’s calendar, attach the agenda, send the invite, and fix the clash.
An AI wrapper packages a model into a useful product. An agent harness is the software around a model that manages its execution: tools, repeated steps, context, progress, and controls. In a simple wrapper, the human often coordinates the rest of the job. A well-designed harness can coordinate more of those steps, within the access and authority you give it.
That is the practical answer to agent wrapper vs. harness. But these are overlapping terms, not two official product categories. A wrapper can contain a harness. A harness can power a chat interface. Neither label tells you whether the product will actually finish your work.
The question to ask: after the AI gives its first answer, who gathers the missing information, takes the next action, checks the result, and handles the exception?
What is an AI wrapper? What is an agent harness?
Conceptual patterns. A single product can combine all three; its interface does not tell you how it works.
An AI wrapper makes a model useful for a particular task
A wrapper is application software that gives you a convenient way to use an underlying AI model. It might provide a form, a set of templates, saved preferences, access to your documents, or a familiar interface inside a tool you already use. An email-writing app is a straightforward example: enter the situation, choose a tone, and receive a draft.
“Thin wrapper” usually means the application adds relatively little beyond the model call. The word “wrapper” is also used much more broadly, sometimes as an insult. That broad usage hides differences between products. An application with excellent accessibility, trusted data, useful integrations, or a well-designed review process may create considerable value even if someone calls it a wrapper.
Think of a recipe app. Turning “I have tomatoes, eggs, and twenty minutes” into an appropriate recipe is useful. You may want to do the cooking yourself. The product does not need to organise your kitchen to justify existing.
An agent harness manages how an AI system works
A harness supplies the machinery that lets a model act as part of a running system. It can expose tools, execute permitted requests, return results to the model, preserve useful state, and decide when execution should continue or stop. LangChain’s definition is deliberately broad: the harness comprises the code, configuration, and execution logic outside the model.
For the kitchen analogy, imagine a cooking station that makes ingredients and utensils available, tracks what has already happened, runs timers, and checks a dish against requirements. The model helps choose the next action; the surrounding system makes the action possible and supplies feedback. The machinery still needs to be designed for the kitchen it operates in.
That last detail matters. A harness is not a magical layer that turns a weak model into an expert, and it is not necessarily a team of agents. A single model running with a small, well-chosen set of tools can be enough.
Where does ordinary automation fit?
There is a third option: a fixed workflow. If every new form submission should create a spreadsheet row and send the same acknowledgement, conventional automation may do the job with fewer moving parts. An AI step can classify or summarise the submission without being allowed to redesign the entire process.
Anthropic distinguishes workflows from agents by who directs the sequence: predefined code paths in a workflow, versus a model dynamically directing its process and tool use in an agent. A harness can support either approach, including a mixture. More autonomy is a design choice, not a prize.
AI wrapper vs. agent harness: the practical differences
The table compares a thin, answer-focused wrapper with a harness built for a multi-step job. It describes design patterns, not universal rules about everything sold under either name.
| Question | Thin wrapper | Task-oriented harness |
|---|---|---|
| What does it deliver? | An answer, draft, or transformation. | A managed sequence of actions toward a defined result. |
| Who moves work forward? | Usually the user between requests. | The execution loop, using model decisions and programmed rules. |
| Where is progress kept? | Often in the chat or the user’s head. | In task state, records, files, or checkpoints if implemented. |
| What happens after a tool fails? | The user may investigate and try again. | A configured retry, alternative path, stop, or escalation. |
| Who can approve actions? | The user reviews the answer and acts. | Permission rules and review gates can block execution. |
| How is “done” established? | The requested output has been returned. | Evidence is checked against the task’s completion criteria. |
| What does it cost to maintain? | Often fewer integrations and operational dependencies. | Potentially more tool, monitoring, review, and recovery work. |
A sophisticated wrapper may have every capability in the right-hand column. At that point, the argument about its name is less useful than an honest demonstration of how it behaves.
Five everyday examples of wrappers and harnesses
These are hypothetical product designs, not claims that a particular app offers every feature. In each example, the model may be equally capable. What changes is the work the surrounding application can manage.
1. Booking a meeting: the invitation is only one step
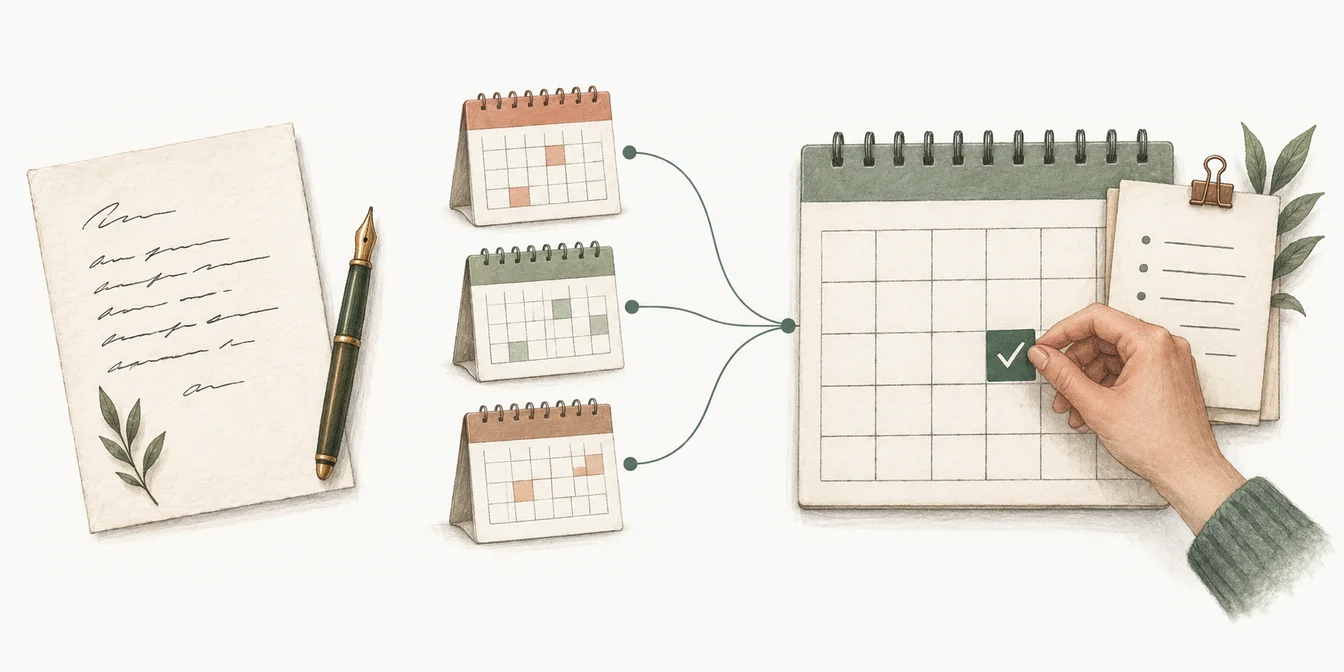
With a wrapper: you ask for a friendly invitation to a project review. It writes the message. You check calendars, remember the time zones, find the agenda, and send it yourself. If someone declines, you reopen the process.
With a harness: the system reads the calendars it is allowed to access, identifies available slots, prepares the event, attaches the correct agenda, and requests any required approval before sending. It checks that the calendar service actually created the event. If access to one calendar is missing, it reports the gap instead of claiming everybody is free.
The boundary is visible: “I wrote an invitation” and “the approved meeting exists in the calendar” are different completion criteria. A product should say which one it has achieved.
2. Handling a customer return: a polite reply is not a resolved case
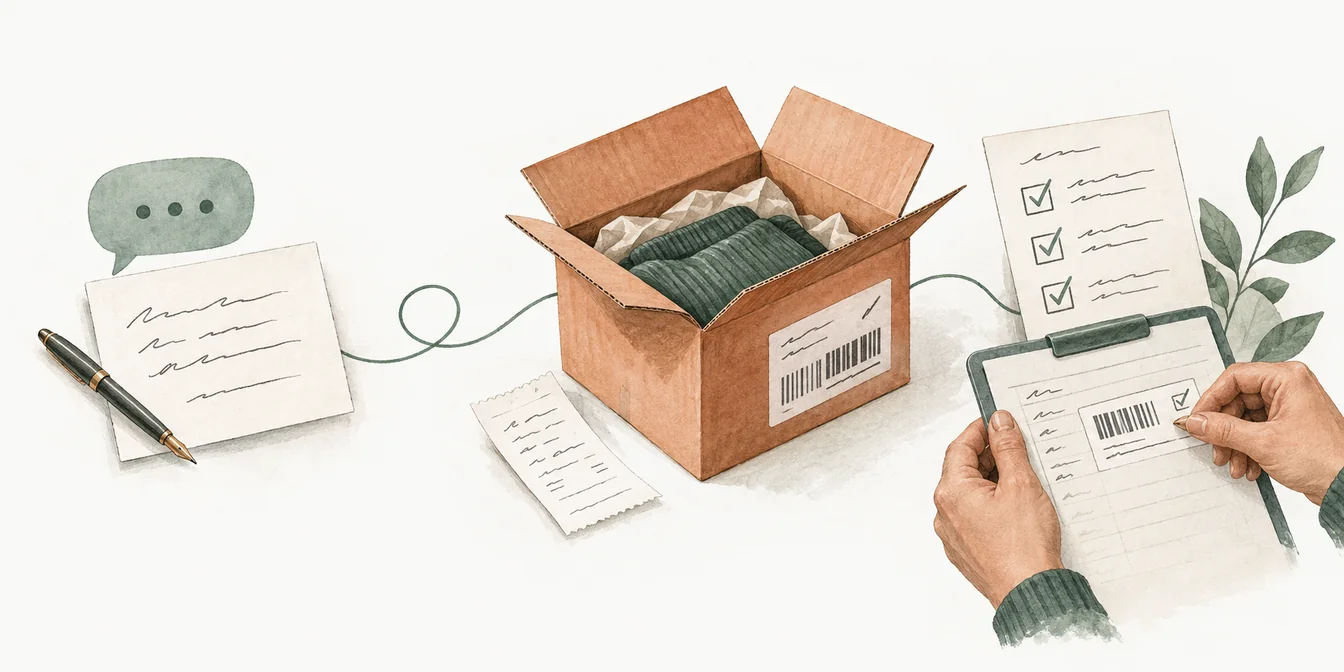
With a wrapper: paste a customer complaint and get an empathetic response. You still find the order, check the store’s return policy, inspect the delivery record, and decide the next step.
With a harness: the application retrieves the order and relevant policy, identifies missing information, prepares an appropriate action, and routes exceptions to a person. If a return label is approved, it requests the label and records its reference. If the tool times out, it checks whether the label was already created before repeating the request.
That small exception is where much of the engineering lives. A confident message saying “your return is arranged” is harmful when the actual return record does not exist. The system needs evidence from the store’s tools, not just plausible language.
3. Preparing a weekly report: writing is not reconciliation
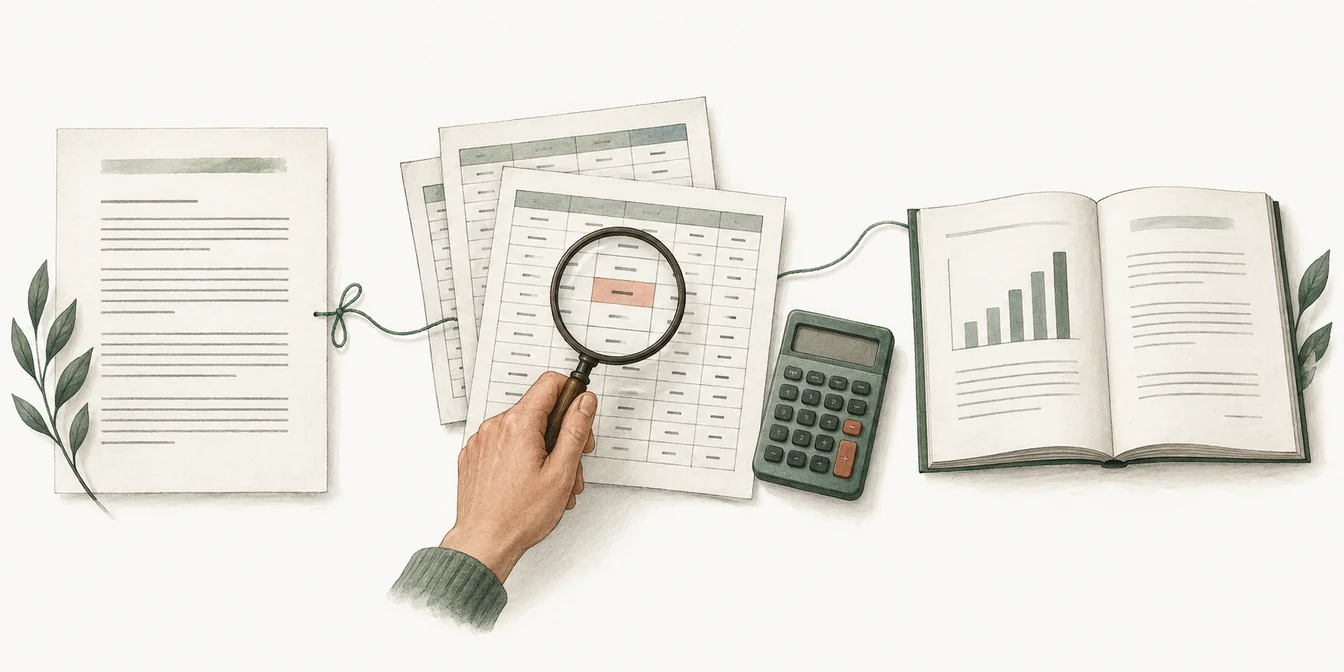
With a wrapper: upload a spreadsheet and ask for a summary. You receive a readable account of the numbers you supplied. If last week’s file was uploaded by mistake, a well-written summary can still be wrong for this week.
With a harness: the process obtains the specified reporting period, checks dates and required fields, performs calculations, builds a draft, and records the source files. If two departments use different definitions of “active customer”, it flags the discrepancy instead of quietly combining them.
A simple fixed workflow may be the better implementation when the sources and calculations never change. The agent earns its place when it needs to investigate a missing file or interpret an unfamiliar exception. Arithmetic itself does not need creative judgement.
4. Planning a trip: recommendations versus a checked plan
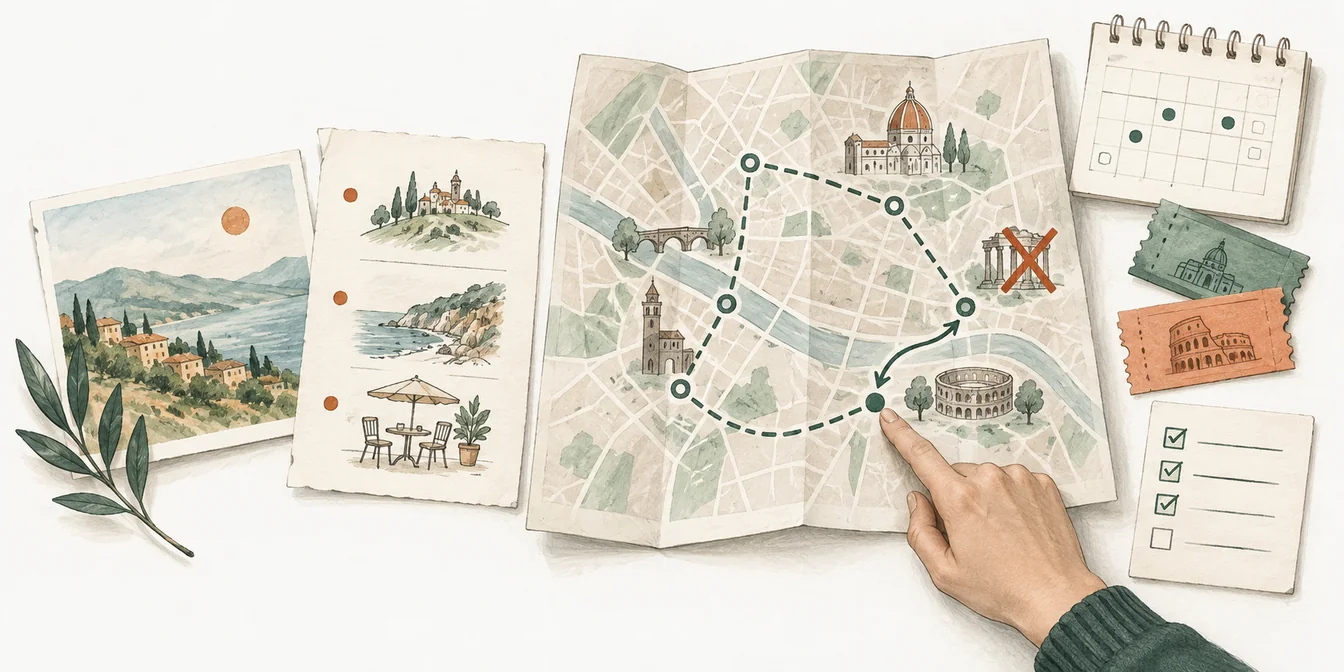
With a wrapper: ask for a three-day itinerary and receive places to visit. You check opening times, travel distances, availability, and your own budget.
With a harness: the system can look up current information, compare the dates against your constraints, revise the plan when a museum is closed, and assemble a booking shortlist. It can pause before any purchase and record what you approved.
A sensible version may stop at a verified shortlist. It does not need permission to spend money to be useful. “More autonomous” would not automatically mean “better for your holiday”.
5. Publishing a blog: generating paragraphs versus preparing a page
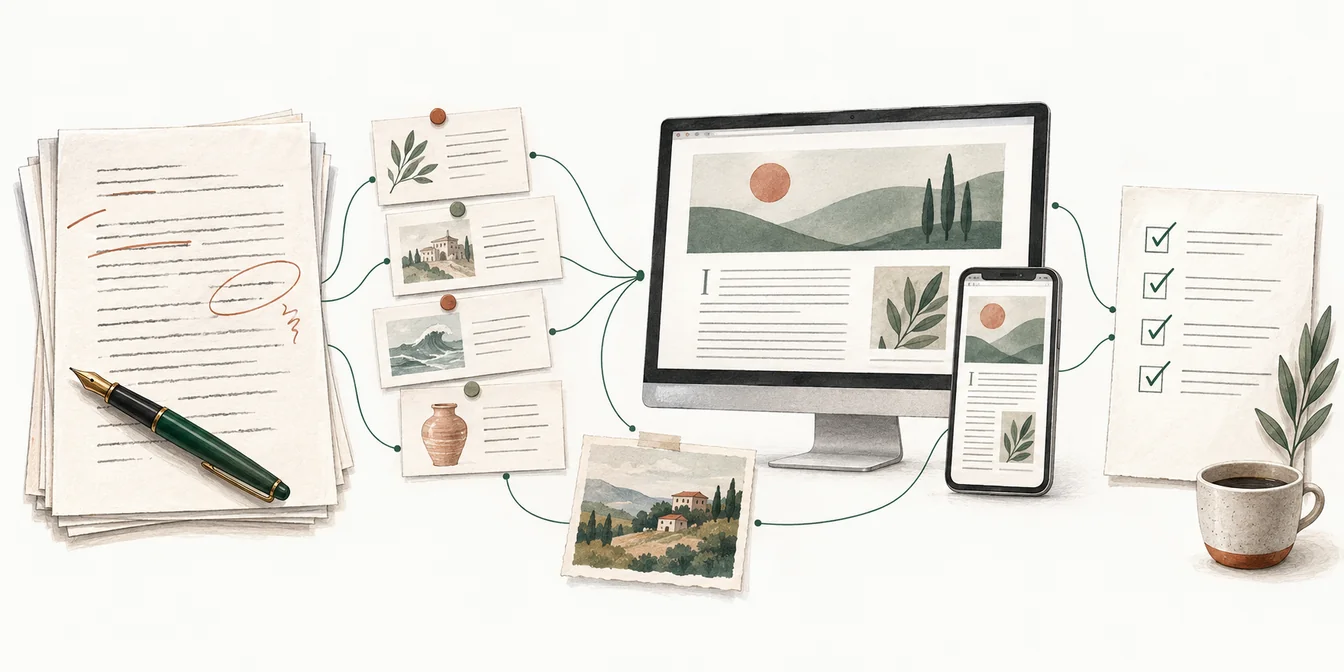
With a wrapper: you get a draft article. You handle citations, formatting, images, links, previews, and the website update.
With a harness: the system can consult the site’s writing instructions, research claims, prepare images, create the page, check metadata, and inspect a preview. Publishing remains a separate action governed by the owner’s authorization. A missing image or broken mobile layout becomes something to fix before completion.
The workflow benefits from a reusable writing skill, but the skill alone is not the harness. The skill describes how to work. The harness loads those instructions, provides tools, runs the process, and manages its state.
Follow one job past the first answer
Choose a task. The upper path shows an answer-focused wrapper; the lower path shows a possible managed workflow.
- Describe the meeting
- Receive an invitation draft
- You coordinate the rest
- Read permitted calendars
- Check slots and time zones
- Prepare event and agenda
- Obtain required approval
- Create and verify event
Exception: if a calendar is unavailable, show whose availability is unknown.
Illustrative workflows. Actual capabilities depend on integrations, permissions, and the product’s implementation. The five written examples above remain available without JavaScript.
What happens inside an agent harness?
Picture a receptionist’s desk during a busy morning. There are requests, a diary, contact records, rules about what can be promised, and a list of unfinished jobs. The value comes from connecting those things while keeping track of what actually happened.
The following six responsibilities are a useful checklist for a task-oriented system. They are design requirements to evaluate, not features automatically guaranteed by the word “harness”.
1. An execution loop
The system gives the model the current situation, receives its proposed next step, executes an allowed action, and returns the result. It can repeat this cycle until the task meets its conditions, needs help, or reaches a limit. A maximum number of steps, time budget, or cost budget prevents “keep going” from turning into an endless process.
2. Tools and an operating environment
The model can propose looking up an order; application code must actually connect to the store and return the result. Access may be read-only, restricted to certain records, or unavailable altogether. A tool’s presence does not establish authorization to use it for every purpose.
For ordinary users, ask the concrete question: can this product read the document, update the record, or create the draft where the work actually lives? If you must copy everything between applications, much of the coordination still sits with you.
The model proposes actions. The harness supplies tools, executes permitted requests, and returns feedback.
3. Context and durable progress
Context is information available to the model now. Durable state is information the system saves so it can resume later. For a return, that might include the order reference, the agreed action, the pending approval, and the label already created. A long transcript alone is a poor substitute for an accurate case record.
LangGraph’s persistence documentation describes checkpoints that save graph state at execution steps. The product still needs to choose what to save, how to identify the task, and what information is appropriate to load on resumption.
4. Permission boundaries and human review
“Please ask before sending” is an instruction. An actual approval gate prevents the send operation until approval arrives. These controls should agree, but they are not interchangeable. A useful system can prepare work freely within its scope while keeping specific actions behind explicit authorization.
LangGraph’s interrupt mechanism, for example, supports pausing execution and resuming with external input. Designing the review screen, checking the approver, and ensuring the approval applies to the exact proposed action remain application responsibilities.
A saved record is not the same as a long chat. An approval gate controls execution, not just the wording of a prompt.
5. Verification and recovery
A completion message should be backed by something observable: the event exists, the report totals reconcile, or the page loads correctly. Anthropic’s long-running agent experiments used progress records, incremental work, and explicit testing to address failures such as stopping too early or leaving unclear work behind.
Recovery needs equal care. Retrying a read is different from repeating an action that may already have succeeded. If the calendar service created an invite but the response was lost, a blind retry can create a duplicate. The application should check existing state or use an operation identifier the service can recognise.
6. A record of what happened
When something goes wrong, “the AI did it” is not enough. A useful record identifies the source data, relevant actions, tool results, and approvals. It lets a person investigate a missed step and helps the builder improve the system. Access and retention policies still matter; recording everything forever is not the goal.
Keep a record of the action, evidence, and decision. A timeout does not prove that an external action failed.
Why a good answer is not a completed job
A multi-step task creates more opportunities for a mistake. Imagine a workflow where each necessary step has the same probability of being correct, and the errors are independent. If every step must succeed, the probability of completing the whole chain correctly is the per-step probability multiplied by itself once for each step.
At 95% per step, a ten-step chain has about a 60% chance of every step succeeding on the first pass. That is arithmetic under a simplified assumption, not a measured failure rate for AI products. Real errors can be related, and verification, recovery, or human review can change the outcome.
What happens as a task gets longer?
This toy model assumes identical, independent steps, no retries, and no correction. Change the inputs to see the effect.
59.9% chance that all 10 steps succeed on the first pass.
See the numbers and formula
Formula: 0.95 raised to the power of 10 = 59.9%.
| Steps | First-pass success |
|---|---|
| 1 | 95.0% |
| 5 | 77.4% |
| 10 | 59.9% |
| 20 | 35.8% |
An illustrative probability model, not a wrapper-versus-harness benchmark. It shows why longer chains need checks; it does not estimate the benefit of a harness.
The lesson is to locate failures, not simply add more steps. A return workflow might validate the order before composing its reply. A report might check dates before generating the narrative. Each check is useful only if it can catch the relevant problem and lead to a sensible response.
Even an agent reviewing its own answer may repeat the same mistaken assumption. Checks grounded in records, rules, calculations, or tests are often more informative than another request to “think carefully”. For ambiguous decisions, a person may still be the best reviewer.
Do you need a wrapper, a workflow, or an agent harness?
Start with the amount of coordination your task needs. Rewriting a paragraph is bounded and easy to inspect. Following up on an unresolved customer issue involves state, multiple tools, and exceptions. Treating both as the same purchase leads to either overengineering or disappointment.
Describe the work you want help with
A wrapper may be enough if you can inspect the output and handle the remaining steps yourself.
A rule-based starting point, not a product score or a guarantee. For a fixed sequence, consider ordinary automation. For changing paths, evaluate a harness with relevant tools, state, checks, and limits.
Ask for a demonstration of the awkward case
Most demos show the expected path. Ask what happens when a file is missing, a permission expires, a tool responds slowly, or a person changes the request midway. Can the system explain what is complete, what is uncertain, and what still needs you? Can it resume without repeating an external action?
Ask to see the definition of done. “Prepare a report” could mean a draft exists, the calculations are validated, a manager has reviewed it, or the final version has been distributed. A useful product makes that boundary explicit before it starts.
Compare the cost of an accepted result
Compare these costs per accepted job. A low price per draft does not tell you the cost of completing the work.
Subscription price and model usage are only part of the cost. Include time spent reviewing, reconnecting tools, correcting output, and investigating failed runs. A more capable system may save coordination time while adding operational complexity. A simpler tool may be the better purchase for occasional, easy-to-review tasks.
For a pilot, track completed-and-accepted jobs, review minutes per job, exceptions requiring a person, and total running cost. Decide what “accepted” means in advance. An app that produces fifty drafts has not necessarily resolved fifty cases.
Are agent harnesses the new GPT wrappers?
Greg Isenberg’s post about agent harnesses frames the opportunity as a shift from selling software to selling completed work. An indexed copy of the post was accessible during research; the original X page was not. That is a useful business lens, but it should not turn implementation choices into promises.
The appeal is easy to understand. A shop owner cares about a correctly handled return more than another message-writing screen. A team lead cares about an accurate report more than how many paragraphs were generated. Pricing around an agreed result can align with those needs, provided the result can be measured and exceptions are handled honestly.
Four qualifications matter:
- Model switching is not automatically frictionless. You still need to test instruction-following, tool calls, cost, speed, and quality with each supported model. Keeping business rules outside the model can help, but does not establish equivalence.
- Corrections do not automatically become reliable learning. A system must capture feedback, decide whether it generalises, update the appropriate instruction or rule, and test for regressions. One customer’s preference should not silently become everybody’s policy.
- “Finished work” requires an agreed boundary. Preparing a return label, obtaining customer confirmation, and receiving the returned item are different events. Outcome pricing needs clear acceptance criteria and a plan for events outside the agent’s control.
- A harness is not a guaranteed competitive advantage. Useful domain knowledge, dependable integrations, distribution, trust, and operating economics still matter. A category name cannot protect a business from competitors.
For founders, the opportunity is to understand a recurring job deeply enough to make it dependable. Start with a bounded task, observe where people intervene, and improve those points. An impressive autonomous demo is a starting hypothesis. Repeatedly accepted work is stronger evidence.
For users, the choice is simpler: buy the amount of coordination you need. A good draft can be the whole deliverable. When the deliverable spans several applications and decisions, look for a system that can track and verify that work, and show you where its responsibility ends.
Frequently asked questions
What is the difference between an AI wrapper and an agent harness?
An AI wrapper packages a model into an application. An agent harness manages the model’s execution, including tools, repeated steps, context, and controls. The terms overlap: a wrapper can include a harness.
Is an AI wrapper bad?
No. A focused tool can be valuable when it makes a bounded task easier, offers useful data or integrations, or fits a user’s workflow. Judge the result and the work left for the user, not the label.
Does an agent harness automatically remember and learn?
No. A harness can save progress and load relevant information, but those mechanisms must be implemented. Learning from corrections also requires deciding what to retain and checking that updates improve future work.
Is a harness the same as an agent framework?
Not exactly. A framework supplies building blocks for agent applications. A harness is the execution machinery assembled around a model. Some frameworks include a ready-made harness, while others let you build one.
Does an agent harness need multiple models or multiple agents?
No. A harness can work with one model and one agent. Routing across models and delegating to additional agents are optional choices that add coordination and testing requirements.
When is ordinary automation better than an AI agent?
When the sequence and rules are predictable, a fixed workflow may be simpler to test and maintain. An agent becomes more useful when the next step depends on interpreting changing information or investigating exceptions.
Can a harness guarantee that an AI job is finished correctly?
No. It can provide checks and evidence against defined completion criteria. Reliability still depends on the model, tools, data, validation, and handling of exceptions. Some tasks should end with human review.
Related reading
- How reusable skills guide a coding agent’s work
- Memory tools and context across agent sessions
- A multi-tool content workflow in practice
Working out what your AI product should own?
Talk through the customer’s job, the product’s promise, and how to demonstrate a result people value.
Book a growth chat
Sources checked September 14, 2026. Technical references are linked beside the claims they support: LangChain on harness architecture and persistence, LangGraph on interrupts, and Anthropic on workflow design and long-running agents. The discussion of Greg Isenberg’s post uses the linked indexed copy because X was inaccessible. Everyday scenarios are illustrative product designs. The probability chart is a hypothetical calculation, not performance data. The editorial illustrations were generated with AI for this article; labelled diagrams are conceptual explanations.